Environments – Mobile Robotics
Mobile robot navigation and locomotion tasks for Isaac Sim 6.1.0 with Isaac Lab 3.0.0.
Aerial (_aerial)
Template environment for aerial mobile robots. Configure via
env.robot=<aerial_robot>.
Simulation only; no trained policy ships.
| Episode Length | 10.0s (250 steps) |
| Reward Terms | 1 |
| Default Robot | Ingenuity |
Robots
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.1 | – |
Ground (_ground)
Template environment for ground mobile robots. Configure via
env.robot=<ground_robot>.
| Episode Length | 10.0s (250 steps) |
| Reward Terms | 1 |
| Default Robot | Cadre |
Robots
Anymal C | Anymal D | Random Anymal Quadruped | Cadre | Cassie | Husky | Leo Rover | Mars Rover | Nifty | Open Source Rover | Perseverance | Pragyan | Raph Rover | Spot | Unitree A1 | Unitree Go1 | Unitree Go2 | Random Unitree Quadruped
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.1 | – |
Orbital (_orbital)
Template environment for orbital mobile robots. Configure via
env.robot=<orbital_robot>.
| Episode Length | 10.0s (250 steps) |
| Reward Terms | 2 |
| Default Robot | Cubesat |
Robots
Floating Platform | Int Ball1 | Int Ball2 | Apollo Lander | Peregrine Lander | Vikram Lander | Resilience Lander | Random Lander | Iss | Gateway | Cubesat | Satellite Mockup | Venus Express | Starship | Super Heavy
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.1 | – | |
| penalty_fuel_consumption | Linear | -1 | – |
Camera clipping. Set env.camera_clipping_range=[near,far] to override the render far plane and uint8 depth quantization; depth beyond far saturates and geometry is omitted from RGB.
| Environment | Far plane | Reason or limit |
|---|---|---|
| Orbital default | 100 m ((0.01, 100.0) m) | Orbital robots define no clipping range. |
rendezvous | 50 m | max_target_distance; about 20 cm per uint8 depth step, versus 39 cm at 100 m. |
orbital_evasion | 150 m | 100 m bounds radius plus obstacle field. |
landing, moonfall | 400 m | Nadir camera reaches 200–220 m above terrain, tilted up to 30°. |
Aerial Navigation (aerial_navigation)
Aerial navigation to a dynamic waypoint with terrain-clearance tracking
Simulation only; no trained policy ships.
| Episode Length | 60.0s (1500 steps) |
| Reward Terms | 7 |
| Default Robot | Ingenuity |
Robots
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.1 | – | |
| reward_altitude_tracking | HyperbolicTracking | 4 | 1 | |
| reward_waypoint_approach | Hyperbolic | 16 | 2 | |
| penalty_tilt_angle | OffsetLinear | -2 | – | |
| reward_terrain_clearance | HyperbolicBarrier | 8 | 0.5 | |
| penalty_energy | Linear | -0.5 | – | |
| reward_waypoint_reached | Threshold | 32 | – |
Bounded evaluation. Aerial Navigation and linked tasks omit success; bounded evaluation reports return only.
Beam Transport (beam_transport)
Two-robot collaborative transport of a rigid beam payload to a target point
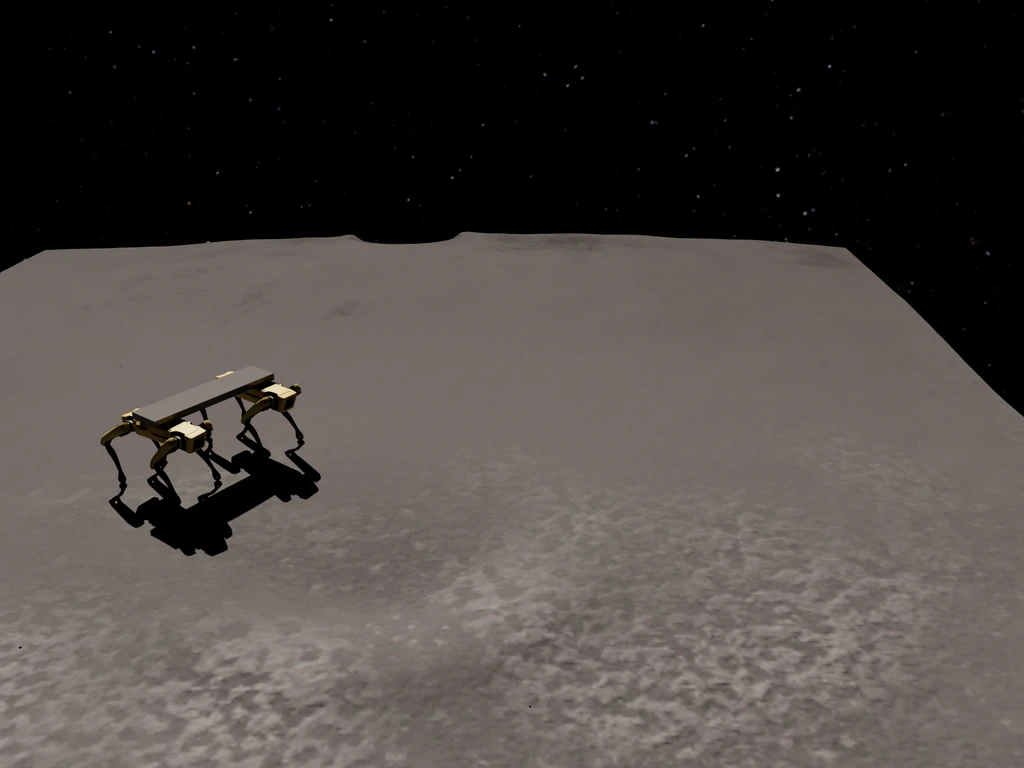
Two Spot quadrupeds carry a rigid beam to a target on procedural MoonSurface. One shared policy observes robots in fixed order and splits one joint action across them, as in formation following.
beam_kinematic_mount_enabled | Behavior |
|---|---|
true (default) | Mount beam at pair midpoint and heading, level at fixed height. Reward shapes support-slot alignment and gentle transport; no grasp/contact dynamics, tilt/drop penalties, or tilt success gate. |
false | Free-beam ablation; restores tilt/drop penalties and tilt success gate. |
No trained policy ships. Train and evaluate with:
srb agent train --algo dreamer --env beam_transport
srb agent eval --algo dreamer --env beam_transport --model <path/to/checkpoint>
Rollouts report min_beam_distance_to_target (m), success-hold streak, and success_rate. At zero success, minimum distance shows partial progress.
| Episode Length | 30.0s (750 steps) |
| Reward Terms | 15 |
| Default Robot | Spot |
Robots
Anymal C | Anymal D | Random Anymal Quadruped | Cadre | Cassie | Husky | Leo Rover | Mars Rover | Nifty | Open Source Rover | Perseverance | Pragyan | Raph Rover | Spot | Unitree A1 | Unitree Go1 | Unitree Go2 | Random Unitree Quadruped
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.1 | – | |
| reward_beam_position | Gaussian | 16 | 1.5 | |
| reward_beam_midpoint_alignment | Gaussian | 10 | 0.25 | |
| reward_robot_support_slots | Gaussian | 12 | 0.2 | |
| reward_beam_progress | Scaled | 8 | – | |
| reward_attachment_balance | Gaussian | 4 | 0.15 | |
| reward_success | Linear | 24 | – | |
| penalty_beam_tilt | Linear | -4 | – | |
| penalty_beam_drop | Linear | -16 | – | |
| penalty_beam_speed | Linear | -2 | – | |
| penalty_joint_torque | Linear | -0.000025 | – | |
| penalty_joint_acceleration | Linear | -0.00000025 | – | |
| penalty_undesired_lin_vel_z | Linear | -0.5 | – | |
| penalty_undesired_ang_vel_xy | Linear | -0.1 | – | |
| penalty_gravity_rotation_alignment | Linear | -2 | – |
Success limits. Hold target pose for success_hold_steps=8 steps (0.32 s); target distance ≤ target_zone_radius_xy=0.20 m; beam-to-midpoint and support-slot alignment ≤ beam_attachment_radius_xy=0.30 m; planar speed ≤ target_speed_threshold_xy=0.35 m/s. Free-beam mode also requires 1 - |cos θ| ≤ beam_tilt_tolerance=0.20 (θ ≲ 37° from vertical). Holding success terminates the episode; otherwise it truncates at 30 s. Resets preserve robot spacing with a shared planar offset within ±1.5 m and shared yaw over the full circle; the mounted beam follows the transformed pair.
Policy spaces. Observations: per-robot planar position, velocity, and beam offset; beam position and 6D rotation; beam-target offset and distance; assignment-invariant support-slot error; beam planar/angular velocity; pair midpoint. Positions are environment-relative; inter-body offsets are unchanged. Actions drive both Spot quadrupeds. The reward table includes per-robot penalties for joint torque/acceleration, vertical velocity, roll/pitch rate, and projected-gravity alignment.
Episode-end info publishes success; bounded evaluation reports success rate and return.
Flight (flight)
Generic powered aerial flight profile with takeoff, transfer, and final landing
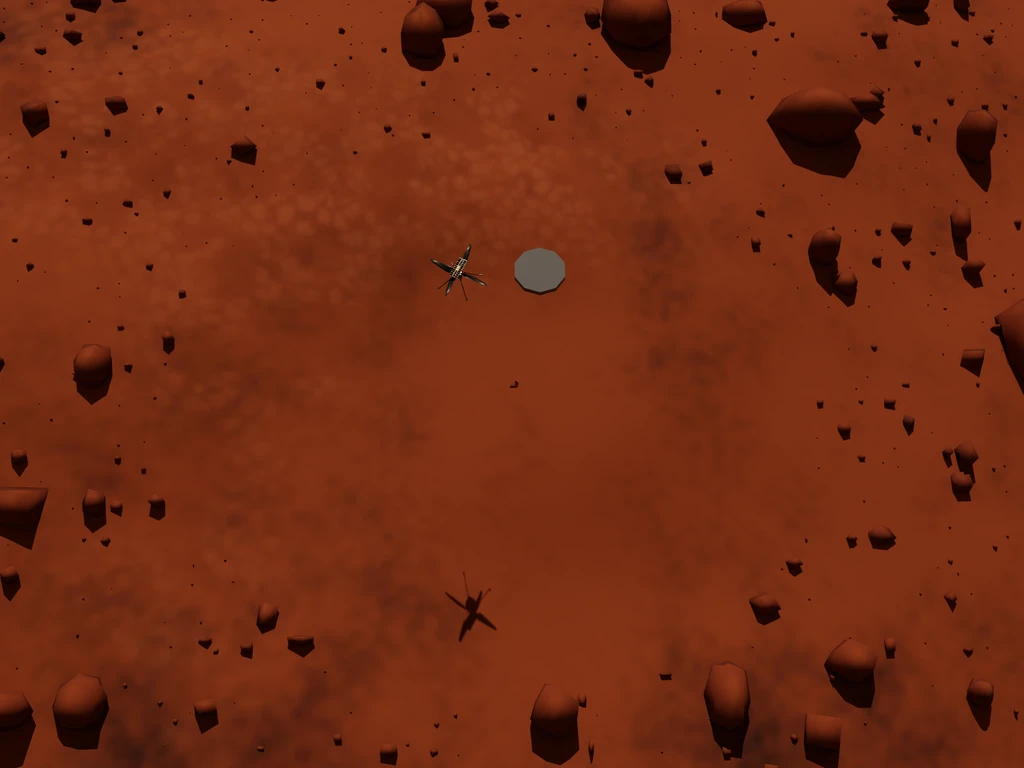
Flight: 90 s Martian mission—ascend to cruise altitude, transfer to landing pad, guarded touchdown approach. Mars is default because rotorcraft need atmosphere; see Modelling envelope. Aerial configuration’s domain-selected scenery owns default Mars spawn and clearance.
Set env.landing_only=true to start in final descent phase 2, skipping ascent and transfer. This is the aerial Flight variant; orbital landing is separate.
| Episode Length | 90.0s (2250 steps) |
| Reward Terms | 8 |
| Default Robot | Ingenuity |
Robots
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.1 | – | |
| reward_waypoint_approach | Hyperbolic | 12 | 4 | |
| reward_altitude_tracking | HyperbolicTracking | 6 | 1 | |
| reward_waypoint_reached | Threshold | 20 | – | |
| penalty_tilt_angle | OffsetLinear | -2 | – | |
| reward_terrain_clearance | HyperbolicBarrier | 6 | 0.8 | |
| penalty_energy | Linear | -0.6 | – | |
| reward_mission_progress | Linear | 60 | – |
Termination/success. Crash terminates below termination_min_clearance or above termination_max_tilt. Pad arrival latches success in episode_outcome_info (crashed, on_pad, mission_phase), but episode runs to the limit. Success requires reaching the pad without crashing on the final step. At default weights, reward_mission_progress pays 60 per completed phase each step, more than other terms combined per step.
Formation Following (formation_following)
Multi-robot formation tracking behind a moving formation center
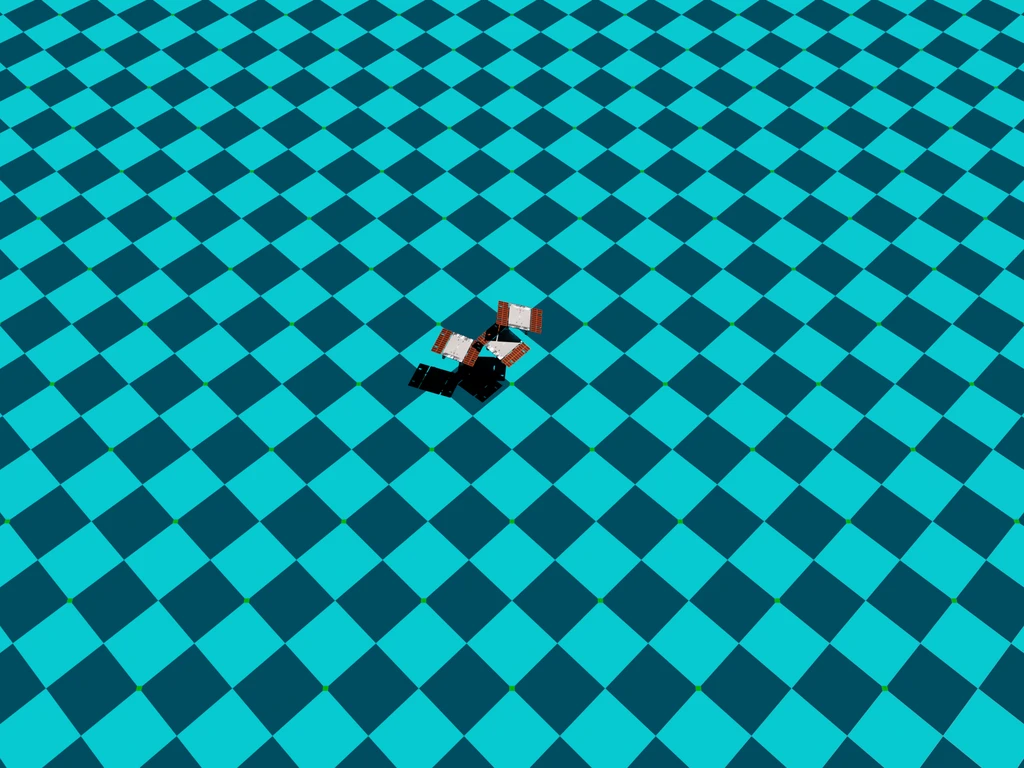
Three Cadre-class rovers follow a drifting center in triangular slots (1.5, 0), (-0.75, 1.3), (-0.75, -1.3) m. Center follows a smooth random walk or ROS formation_center TF.
One shared policy: concatenate observations in fixed rover order, split one joint action across rovers, return one team reward per environment. Observation/action sizes scale linearly with team size. Small teams avoid decentralized communication and role assignment while keeping checkpoints reproducible. Companion centralized surface task: beam transport.
No trained policy ships.
srb agent train --algo dreamer --env formation_following
srb agent eval --algo dreamer --env formation_following --model <path/to/checkpoint>
Rollouts report mean per-rover slot-distance error (formation_distance_error, m), mean heading error (formation_orientation_error, rad), success-hold streak, and success_rate. At zero success, errors show partial progress.
| Episode Length | 60.0s (1500 steps) |
| Reward Terms | 9 |
| Default Robot | Cadre |
Robots
Anymal C | Anymal D | Random Anymal Quadruped | Cadre | Cassie | Husky | Leo Rover | Mars Rover | Nifty | Open Source Rover | Perseverance | Pragyan | Raph Rover | Spot | Unitree A1 | Unitree Go1 | Unitree Go2 | Random Unitree Quadruped
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.1 | – | |
| penalty_formation_tracking | Linear | -1 | – | |
| reward_formation_progress | Scaled | 4 | – | |
| reward_formation_velocity | Linear | 2 | – | |
| reward_point_towards_target | Linear | 0.5 | – | |
| reward_formation_precision | Linear | 4 | – | |
| reward_in_zone | Linear | 0 | – | |
| reward_formation_orientation | Linear | 4 | – | |
| reward_action_rate_in_formation | Linear | 32 | – |
Success limits. All rovers stay within formation_success_position_tolerance_xy=0.20 m of their slots and formation_success_yaw_tolerance≈0.349 rad (20°) in heading for success_hold_steps=8 (0.32 s). Holding success terminates the episode (terminate_on_success=true; formation_following_decentralized keeps running); otherwise it truncates at 60 s. Infinite-horizon (is_finite_horizon=false).
Policy spaces. Each rover observes planar slot offset and heading-to-slot (sin, cos); policy observes center and rover planar velocities. Fixed episodic reset noise: 1 cm position, 2.5° heading. Actions: planar linear/angular velocity.
ROS center. ROS replaces random walk with formation_center TF. First post-reset pose re-anchors center; reset jump is not velocity. Not hardware-validated.
Episode-end info publishes success; bounded evaluation reports success rate and return.
Formation Following Decentralized (formation_following_decentralized)
Single-rover policy view for decentralized formation following
| Episode Length | 60.0s (1500 steps) |
| Reward Terms | 9 |
| Default Robot | Cadre |
Robots
Anymal C | Anymal D | Random Anymal Quadruped | Cadre | Cassie | Husky | Leo Rover | Mars Rover | Nifty | Open Source Rover | Perseverance | Pragyan | Raph Rover | Spot | Unitree A1 | Unitree Go1 | Unitree Go2 | Random Unitree Quadruped
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.1 | – | |
| penalty_formation_tracking | Linear | -1 | – | |
| reward_formation_progress | Scaled | 4 | – | |
| reward_formation_velocity | Linear | 2 | – | |
| reward_point_towards_target | Linear | 0.5 | – | |
| reward_formation_precision | Linear | 4 | – | |
| reward_in_zone | Linear | 0 | – | |
| reward_formation_orientation | Linear | 4 | – | |
| reward_action_rate_in_formation | Linear | 32 | – |
Formation Following Orbital (formation_following_orbital)
Orbital formation tracking in microgravity
| Episode Length | 60.0s (600 steps) |
| Reward Terms | 7 |
| Default Robot | Cubesat |
Robots
Floating Platform | Int Ball1 | Int Ball2 | Apollo Lander | Peregrine Lander | Vikram Lander | Resilience Lander | Random Lander | Iss | Gateway | Cubesat | Satellite Mockup | Venus Express | Starship | Super Heavy
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -8 | – | |
| penalty_fuel_consumption | Linear | 0 | – | |
| penalty_action_magnitude | Linear | -8 | – | |
| penalty_formation_tracking | Linear | -2 | – | |
| reward_formation_precision | Linear | 16 | – | |
| reward_formation_orientation | Linear | 48 | – | |
| reward_action_rate_in_formation | Linear | 48 | – |
Slot assignment. randomize_formation_assignment=false assigns environment i to slot i % N (N formation positions), including partial resets. When true (default), each reset draws a random slot.
Landing (landing)
Landing of spacecraft on planetary surfaces with varying terrain and obstacles
| Episode Length | 40.0s (1000 steps) |
| Reward Terms | 11 |
| Default Robot | Peregrine Lander |
Robots
Floating Platform | Int Ball1 | Int Ball2 | Apollo Lander | Peregrine Lander | Vikram Lander | Resilience Lander | Random Lander | Iss | Gateway | Cubesat | Satellite Mockup | Venus Express | Starship | Super Heavy
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.1 | – | |
| penalty_fuel_consumption | Linear | -1 | – | |
| penalty_angular_velocity | Linear | -0.25 | – | |
| penalty_gravity_rotation_alignment | Linear | -1 | – | |
| penalty_horizontal_linear_velocity | Linear | -0.1 | – | |
| reward_vertical_linear_velocity | Hyperbolic | 8 | 1 | |
| reward_landing_angle | Linear | 8 | – | |
| reward_landing_velocity | Linear | 16 | – | |
| reward_landing_fuel | Linear | 4 | – | |
| penalty_crash | Linear | -32 | – | |
| penalty_below_target | Linear | -16 | – |
See evaluation note.
Event cameras. Add events to env.active_sensors for the onboard (landing, moonfall) or front (velocity_tracking, waypoint_navigation) event camera.
Locomotion Velocity Tracking (locomotion_velocity_tracking)
Locomotion with legged robots and humanoids while tracking desired velocity commands
Simulation only; no trained policy ships.
| Episode Length | 20.0s (500 steps) |
| Reward Terms | 12 |
| Default Robot | Spot |
Robots
Anymal C | Anymal D | Random Anymal Quadruped | Cassie | Spot | Unitree A1 | Unitree Go1 | Unitree Go2 | Random Unitree Quadruped | Humanoid21 | Humanoid28 | Unitree H1 | Unitree G1
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.1 | – | |
| reward_cmd_lin_vel_xy | Linear | 4 | – | |
| reward_cmd_ang_vel_z | Linear | 2 | – | |
| penalty_undesired_lin_vel_z | Linear | -0.5 | – | |
| penalty_undesired_ang_vel_xy | Linear | -0.1 | – | |
| penalty_joint_torque | Linear | -0.000025 | – | |
| penalty_joint_acceleration | Linear | -0.00000025 | – | |
| penalty_undesired_robot_contacts | Threshold | -2 | – | |
| penalty_gravity_rotation_alignment | Linear | -2 | – | |
| reward_feet_air_time | Linear | 0.75 | – | |
| reward_quadruped_trot | Linear | 1 | – | |
| penalty_foot_slip | Linear | -0.5 | – |
Termination matches Locomotion Waypoint Navigation: undesired non-foot contact, fall (planar projected gravity above 0.85), or non-finite state. Time limits truncate.
See evaluation note.
Locomotion Waypoint Navigation (locomotion_waypoint_navigation)
Navigation to a dynamic waypoint with legged robots and humanoids
Simulation only; no trained policy ships.
| Episode Length | 60.0s (1500 steps) |
| Reward Terms | 13 |
| Default Robot | Spot |
Robots
Anymal C | Anymal D | Random Anymal Quadruped | Cassie | Spot | Unitree A1 | Unitree Go1 | Unitree Go2 | Random Unitree Quadruped | Humanoid21 | Humanoid28 | Unitree H1 | Unitree G1
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.1 | – | |
| penalty_position_tracking | Linear | -1 | – | |
| reward_point_towards_target | Linear | 1 | – | |
| reward_position_tracking_precision | Linear | 4 | – | |
| reward_orientation_tracking | Linear | 8 | – | |
| reward_action_rate_at_target | Linear | 16 | – | |
| penalty_joint_torque | Linear | -0.000025 | – | |
| penalty_joint_acceleration | Linear | -0.00000025 | – | |
| penalty_undesired_robot_contacts | Threshold | -2 | – | |
| penalty_undesired_lin_vel_z | Linear | -0.5 | – | |
| penalty_undesired_ang_vel_xy | Linear | -0.1 | – | |
| penalty_gravity_rotation_alignment | Linear | -2 | – | |
| reward_feet_air_time | Linear | 0.5 | – |
Episodes terminate if non-foot contact exceeds its configured undesired-contact threshold, projected gravity’s planar norm exceeds 0.85 (fall), or contact/gravity state is non-finite (fail-closed). Time limits truncate, not terminate.
See evaluation note.
Moonfall (moonfall)
Heavy-weight lunar descent with deployment stage and multi-stage landing phases
| Episode Length | 70.0s (1750 steps) |
| Reward Terms | 12 |
| Default Robot | Peregrine Lander |
Robots
Floating Platform | Int Ball1 | Int Ball2 | Apollo Lander | Peregrine Lander | Vikram Lander | Resilience Lander | Random Lander | Iss | Gateway | Cubesat | Satellite Mockup | Venus Express | Starship | Super Heavy
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.1 | – | |
| penalty_fuel_consumption | Linear | -1 | – | |
| penalty_angular_velocity | Linear | -0.25 | – | |
| penalty_gravity_rotation_alignment | Linear | -1 | – | |
| penalty_horizontal_linear_velocity | Linear | -0.1 | – | |
| reward_waypoint_progress | Hyperbolic | 4 | 4 | |
| reward_vertical_linear_velocity | Hyperbolic | 8 | 1 | |
| reward_landing_angle | Linear | 8 | – | |
| reward_landing_velocity | Linear | 16 | – | |
| reward_landing_fuel | Linear | 4 | – | |
| penalty_crash | Linear | -32 | – | |
| penalty_below_target | Linear | -16 | – |
See event camera options.
See evaluation note.
Orbital Evasion (orbital_evasion)
Navigation of spacecraft in microgravity while avoiding obstacles
| Episode Length | 30.0s (750 steps) |
| Reward Terms | 7 |
| Default Robot | Cubesat |
Robots
Floating Platform | Int Ball1 | Int Ball2 | Apollo Lander | Peregrine Lander | Vikram Lander | Resilience Lander | Random Lander | Iss | Gateway | Cubesat | Satellite Mockup | Venus Express | Starship | Super Heavy
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.1 | – | |
| penalty_fuel_consumption | Linear | -1 | – | |
| penalty_angular_velocity | Linear | -0.25 | – | |
| reward_obstacle_clearance | HyperbolicBarrier | 4 | 2 | |
| penalty_distance_robot_to_target | Linear | -0.32 | – | |
| penalty_out_of_bounds | Linear | -16 | – | |
| reward_target_approach | Hyperbolic | 8 | 5 |
Termination. max_target_distance affects penalty_out_of_bounds, not terminated. Collision terminates when robot center of mass enters an obstacle keep-out sphere (0.5 * obstacle_scale * 1.4; 3.5 m for default 5 m asteroids), i.e. clearance falls below termination_min_obstacle_distance (0 m). Robot is a point: large robots may touch obstacles without termination, and about 7% of asteroids extend beyond the sphere on one axis. Obstacle centers spawn at z ∈ [-43, -7] m, at least 7 m from robot spawn and target. Time limits set truncated.
See evaluation note.
Orbital Waypoint Navigation (orbital_waypoint_navigation)
Navigation to a dynamic waypoint in orbital microgravity
| Episode Length | 30.0s (300 steps) |
| Reward Terms | 9 |
| Default Robot | Satellite Mockup |
Robots
Floating Platform | Int Ball1 | Int Ball2 | Apollo Lander | Peregrine Lander | Vikram Lander | Resilience Lander | Random Lander | Iss | Gateway | Cubesat | Satellite Mockup | Venus Express | Starship | Super Heavy
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | LogCosh | -4 | – | |
| penalty_fuel_consumption | Linear | 0 | – | |
| penalty_action_magnitude | LogCosh | -1 | – | |
| penalty_angular_velocity | LogCosh | -2 | – | |
| penalty_position_distance | Linear | -1 | – | |
| penalty_velocity_at_target | LogCosh | -4 | – | |
| reward_position_approach | Hyperbolic | 4 | 2 | |
| reward_position_precision | Scaled | 8 | – | |
| reward_smooth_station_keeping | Scaled | 8 | – |
See evaluation note.
Rendezvous (rendezvous)
Maneuvering of spacecraft in microgravity to rendezvous with an uncooperative target
| Episode Length | 25.0s (625 steps) |
| Reward Terms | 7 |
| Default Robot | Cubesat |
Robots
Floating Platform | Int Ball1 | Int Ball2 | Apollo Lander | Peregrine Lander | Vikram Lander | Resilience Lander | Random Lander | Iss | Gateway | Cubesat | Satellite Mockup | Venus Express | Starship | Super Heavy
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.1 | – | |
| penalty_fuel_consumption | Linear | -8 | – | |
| penalty_angular_velocity | Linear | -0.05 | – | |
| penalty_distance_robot_to_target | Linear | -16 | – | |
| penalty_too_far | Linear | -16 | – | |
| reward_precision_position | Gaussian | 128 | 0.025 | |
| reward_precision_orientation | Linear | 128 | – |
Termination. Exceeding max_target_distance incurs penalty_too_far but leaves terminated false so the agent can recover. Only the time limit sets truncated.
See evaluation note.
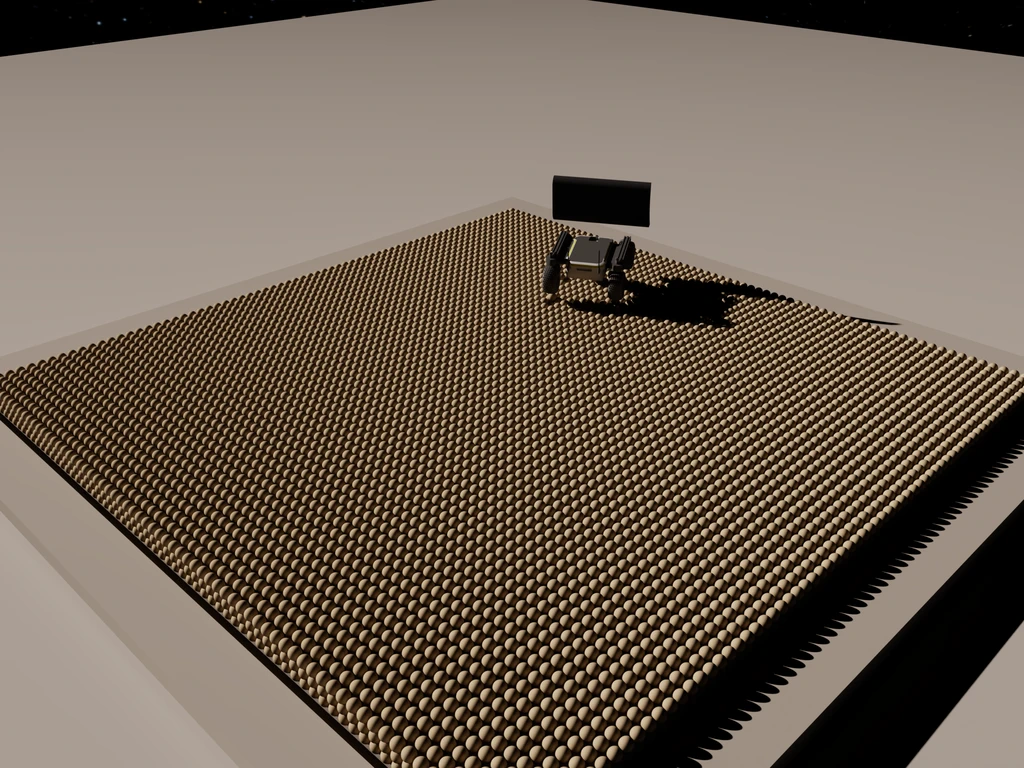
Terrain Landscaping (terrain_landscaping)
Terrain landscaping with a ground mobile robot reshaping a particle bed
No trained policy ships. Dreamer requires
env.num_envs=1; TD-MPC2 is unsupported; Raph hardware validation is incomplete. See Terrain Landscaping Training.
Setup: RaphRover + articulated RaphShovel (env.robot=raph_rover+raph_shovel). Filtered actions, in order: rover linear, rover angular, shovel extension velocity (terms robot/cmd_vel = linear, angular; payload/joint_vel = prismatic). Shovel resets raised at its 0.2 m joint limit; zero velocity holds position via actuator damping, keeping blade above settled particles until policy lowers it.
Reset: rover within ±1.1 m of bed center, random yaw. Blade reaches about 0.53 m from rover origin and starts clear of ±2.0 m walls. Rear-axle Ackermann steering limits yaw rate; full C/V turn gives about half the command.
Teleoperate (one environment):
srb agent teleop -e terrain_landscaping env.num_envs=1
| Input | Action |
|---|---|
W/S, C/V | Forward/reverse; turn. |
Q/E | Raise/lower shovel. Release sends zero velocity; damping resists drift, no auto-retract. |
| SpaceMouse forward/back, vertical | Same channels; rover ignores lateral translation. |
Each episode deforms the flat reset bed with a hashed, mass-balanced mission: cut/fill balance within 1e-4 m³; cuts stay above available material, fills below containment ceiling, significant deformation in reachable zone. Seed (env.general_mission_seed, env_id, episode_index) reproduces missions across processes. Manifest records generator version, seed, frame, geometry, physical bounds, target-map, reset-layout, and manifest hashes. Infeasible missions redraw; exhausted attempts raise. Configure env.general_mission_profile.*.
This task shares only reward implementation and observation contract with terrain_landscaping_crater; targets, manifests, and curriculum stages are separate.
| Episode Length | 60.0s (600 steps) |
| Default Robot | Raph Rover |
Robots
Observation contract. Actor uses external heightmaps, not depth; PhysX particles cannot be raycast. Each policy step publishes one accepted-or-held 10 Hz live-regolith frame. Seven ordered leaves: global current/target (
16×16), rover-frame local current/target (24×16), mission pose(x,y,yaw), body velocity(vx,vy,wz), frame age; flattened to1287 float32. Elevations use mission-frame+z, matching deployment adapters. No validity mask: all146×146source cells finite; incomplete/out-of-envelope frames rejected whole. Unobserved: shovel extension, previous action, particle positions, simulator world pose, privileged current-minus-target maps.env.external_heightmap.profile:ideal,randomized,failure_stale.
Reward/episode. Sole reward 1 / (1 + mae / 0.02) on fixed mission grading cells, shared with crater. MDP continues (is_finite_horizon=false); time limit truncates. Success is evaluation-only, never termination or bonus.
Canonical tasks require RaphRover and RaphShovel; other robots or payloads fail before scene binding. Actor observations and canonical deployment profile omit shovel state.
Frame validity. Map, pose, and velocity share a timestamp; local crop uses that pose. Simulation resets capture one synchronous frame; deployment resets wait up to 2.0 s. A missing frame raises (no zero substitute). Frames older than 0.5 s stale-abort outside MDP. Dropped updates repeat the last complete map and increase frame age.
TD-MPC2 is unsupported because shovel extension is unobserved; it fails with an actionable error before creating logs, config, replay, or model. See Terrain Landscaping Training.
Terrain Landscaping Crater (terrain_landscaping_crater)
Separate deterministic baseline: fill one shallow crater from a nearby regolith pile
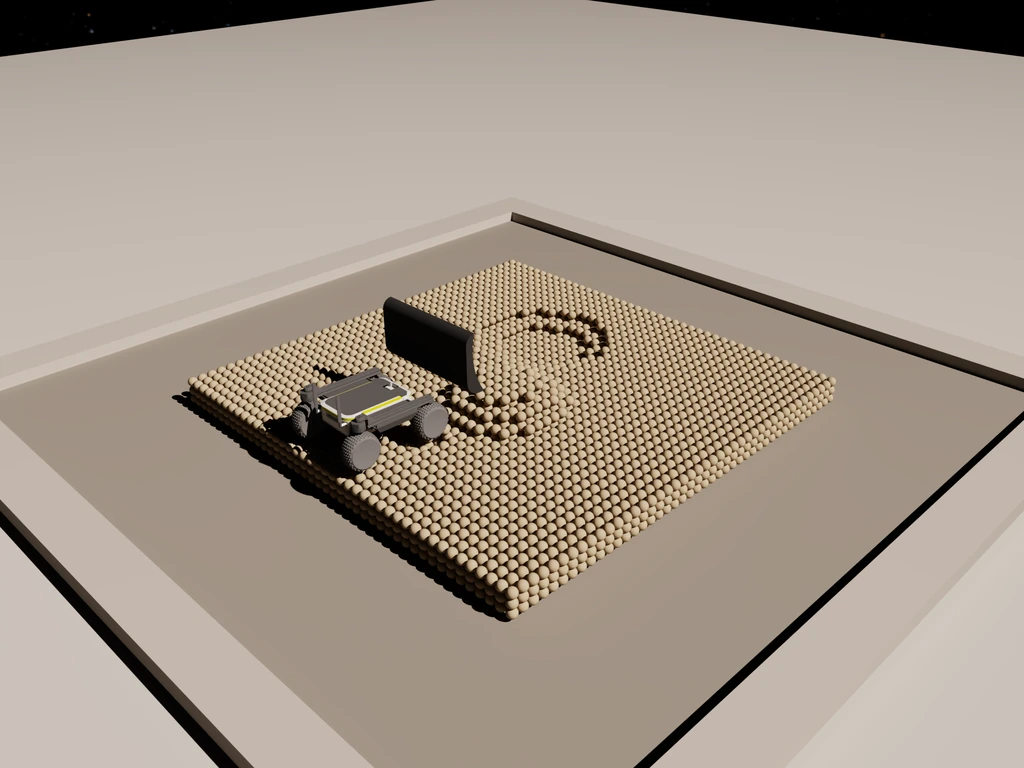
No trained policy ships; Dreamer supports only
env.num_envs=1; TD-MPC2 is unsupported; the task is not validated on Raph hardware. See Terrain Landscaping Training.
Separate deterministic task from terrain_landscaping: no curriculum, scheduler, or automatic switching. Layered bed: one shallow bowl crater and one loose pile; crater particles reused, preserving particle count/mass. RaphRover starts fixed with both forward. Visible 4 m slab below physical ground, dark neutral terrain, and light regolith keep the bed readable against lunar skydome in viewport/headless captures.
Static analytic flat-bed target: crater_target_manifest.json; config fails if crater, pile, or spawner settings cannot reproduce hashed reset layout. Reward: 1 / (1 + mae / 0.02) on fixed manifest grading cells using oracle particle truth. Success: 90% of cells within tolerance for 20 consecutive newly accepted mapper frames; report at time-limit truncation, never termination/bonus. Continuing MDP (is_finite_horizon=false): the time limit truncates; leaving the rover pose/velocity envelope terminates. Physics perturbations/lighting randomization disabled. Action/observation schemas match terrain_landscaping.
Inspect by teleoperation:
srb agent teleop -e terrain_landscaping_crater env.num_envs=1
| Episode Length | 30.0s (300 steps) |
| Default Robot | Raph Rover |
Robots
| Feature | Defaults |
|---|---|
| Crater | Center (0.45 m, 0.20 m), radius 0.36 m, depth 0.11 m. |
| Pile | Center (-0.25 m, -0.20 m), radius 0.32 m, height 0.28 m. |
Override under env.*. Out-of-bed, overlapping, or under-capacity layouts fail before particle spawn.
Observation contract. Same heightmap and frame contract as
terrain_landscaping; schema flattens to1287 float32.
TD-MPC2 has the same unsupported setup and fails before logs, config, replay, or model. PhysX PBD particles require a CUDA-capable NVIDIA GPU; particle state uses CPU readback (sim.device = "cpu") for heightmap, reward, and rendering. See Terrain Landscaping Training.
Terrain Landscaping Mound (terrain_landscaping_mound)
Separate deterministic baseline: level one regolith mound on a flat bed, graded by excess volume
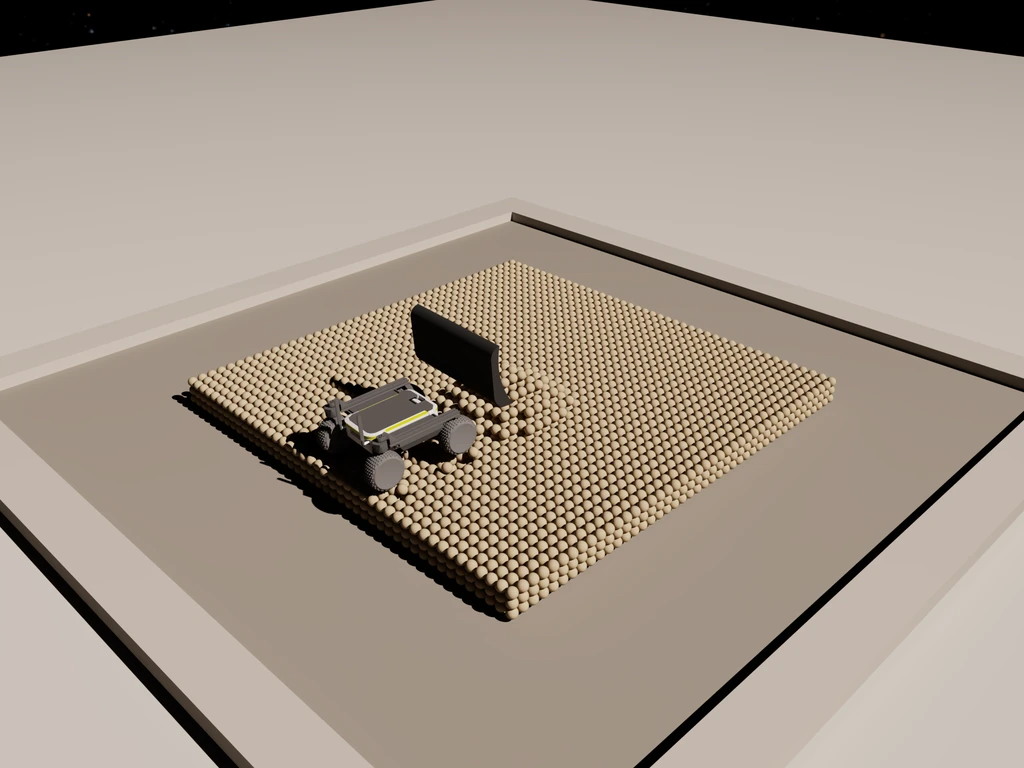
No trained policy ships, Dreamer runs with
env.num_envs=1only, TD-MPC2 is not supported, and the task is not validated on Raph hardware. See Terrain Landscaping Training.
| Episode Length | 30.0s (300 steps) |
| Default Robot | Raph Rover |
Robots
Traversal (traversal)
Straight-line path following at a target velocity
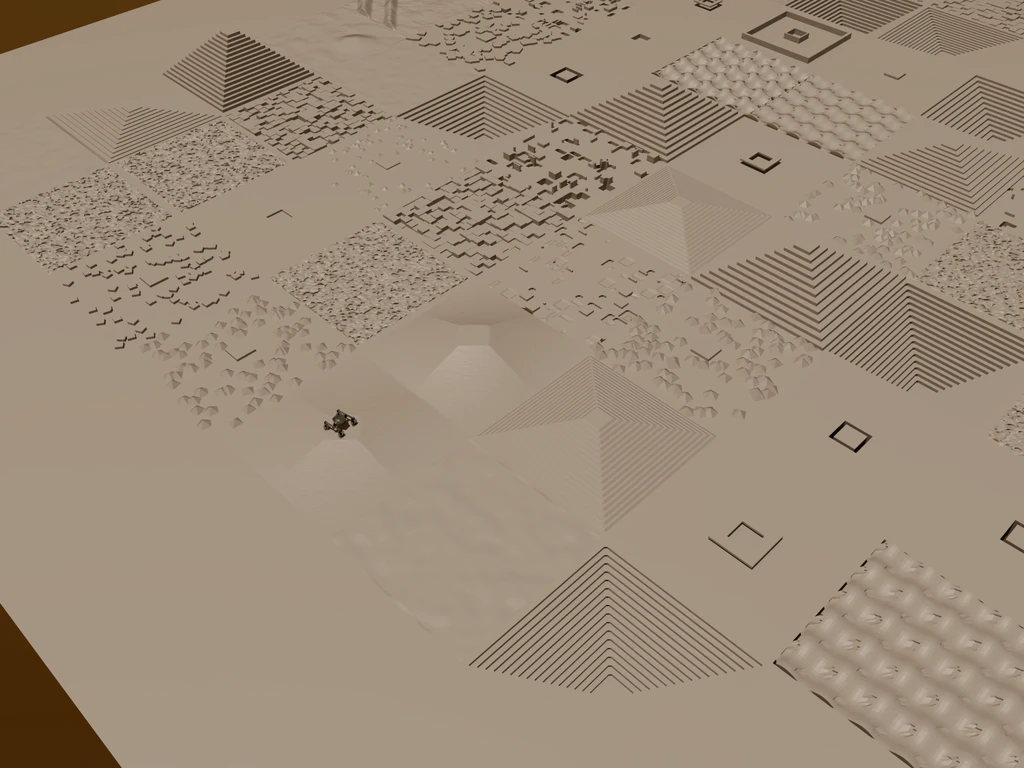
| Episode Length | 120.0s (3000 steps) |
| Reward Terms | 5 |
| Default Robot | Nifty |
Robots
Anymal C | Anymal D | Random Anymal Quadruped | Cadre | Cassie | Husky | Leo Rover | Mars Rover | Nifty | Open Source Rover | Perseverance | Pragyan | Raph Rover | Spot | Unitree A1 | Unitree Go1 | Unitree Go2 | Random Unitree Quadruped
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.05 | – | |
| penalty_lateral_pos_deviation | Linear | -1 | – | |
| reward_vel_progress | Linear | 8 | – | |
| reward_action_rate_at_target | Linear | 32 | – | |
| penalty_rollover | Linear | -16 | – |
Termination. Exceeding max_tilt_rad incurs penalty_rollover but leaves terminated false so the rover can recover. The time limit sets truncated.
See evaluation note.
Velocity Tracking (velocity_tracking)
Basic tracking of desired velocity commands
| Episode Length | 20.0s (500 steps) |
| Reward Terms | 5 |
| Default Robot | Cadre |
Robots
Anymal C | Anymal D | Random Anymal Quadruped | Cadre | Cassie | Husky | Leo Rover | Mars Rover | Nifty | Open Source Rover | Perseverance | Pragyan | Raph Rover | Spot | Unitree A1 | Unitree Go1 | Unitree Go2 | Random Unitree Quadruped
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.1 | – | |
| reward_cmd_lin_vel_xy | Linear | 4 | – | |
| reward_cmd_ang_vel_z | Linear | 2 | – | |
| penalty_undesired_lin_vel_z | Linear | -0.5 | – | |
| penalty_undesired_ang_vel_xy | Linear | -0.1 | – |
Commands (vx, vy, wz) are sampled uniformly in ±1 m/s and rad/s. Wheeled drives use their own limits instead and get no lateral command.
See evaluation note.
See event camera options.
Waypoint Navigation (waypoint_navigation)
Navigation to a dynamic waypoint
| Episode Length | 60.0s (1500 steps) |
| Reward Terms | 6 |
| Default Robot | Cadre |
Robots
Anymal C | Anymal D | Random Anymal Quadruped | Cadre | Cassie | Husky | Leo Rover | Mars Rover | Nifty | Open Source Rover | Perseverance | Pragyan | Raph Rover | Spot | Unitree A1 | Unitree Go1 | Unitree Go2 | Random Unitree Quadruped
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.1 | – | |
| penalty_position_tracking | Linear | -1 | – | |
| reward_point_towards_target | Linear | 1 | – | |
| reward_position_tracking_precision | Linear | 4 | – | |
| reward_orientation_tracking | Linear | 8 | – | |
| reward_action_rate_at_target | Linear | 16 | – |
See evaluation note.
See event camera options.