Environments – Mobile Manipulation
Environments combining mobility and manipulation.
Aerial Manipulation (_aerial_manipulation)
Template environment for aerial mobile manipulators. Configure via
env.robot.mobile_base=<aerial_robot>andenv.robot.manipulator=<manipulator>.
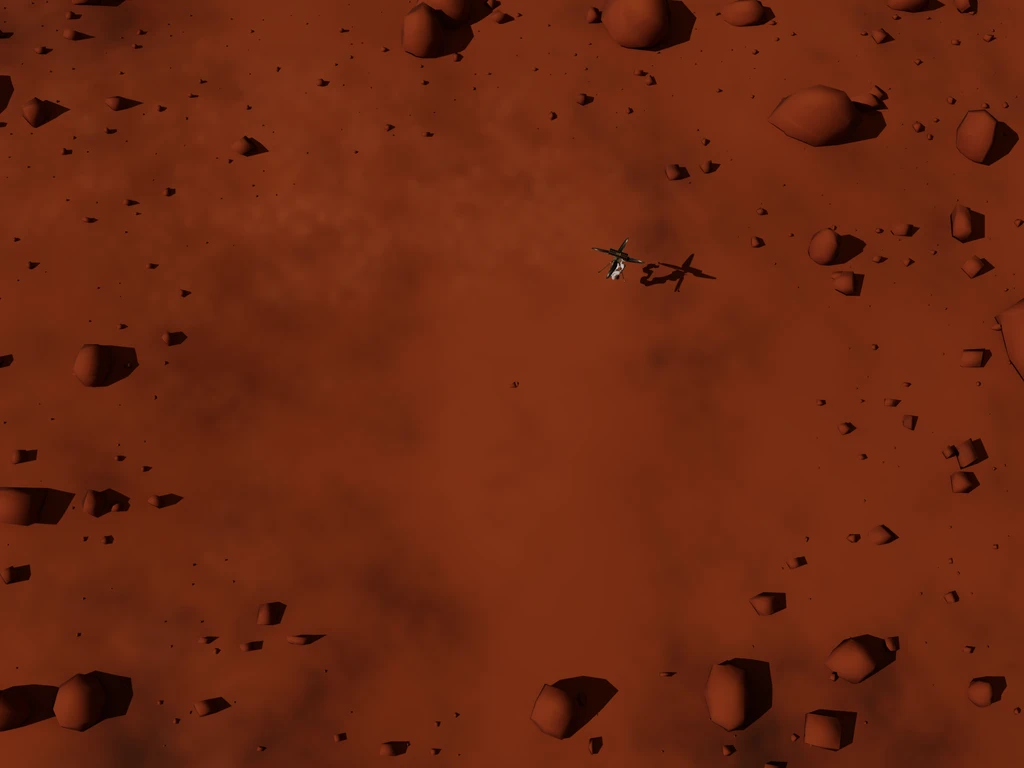
Simulation only; no trained policy ships.
| Episode Length | 10.0s (500 steps) |
| Reward Terms | 2 |
| Default Robot | Generic Aerial Manipulator |
Robots
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.1 | – | |
| penalty_undesired_robot_contacts | Threshold | -0.5 | – |
Ground Manipulation (_ground_manipulation)
Template environment for ground mobile manipulators. Configure via
env.robot.mobile_base=<ground_robot>andenv.robot.manipulator=<manipulator>.
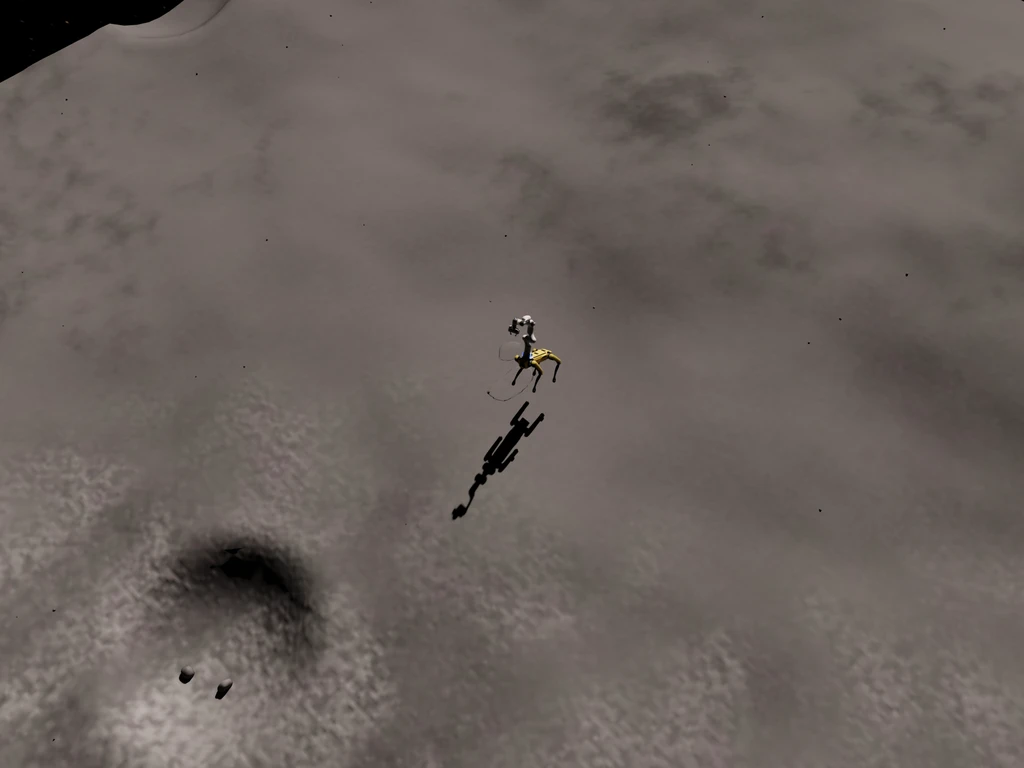
| Episode Length | 10.0s (500 steps) |
| Reward Terms | 2 |
| Default Robot | Generic Ground Manipulator |
Robots
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.1 | – | |
| penalty_undesired_robot_contacts | Threshold | -0.5 | – |
Orbital Manipulation (_orbital_manipulation)
Template environment for orbital mobile manipulators. Configure via
env.robot.mobile_base=<orbital_robot>andenv.robot.manipulator=<manipulator>.
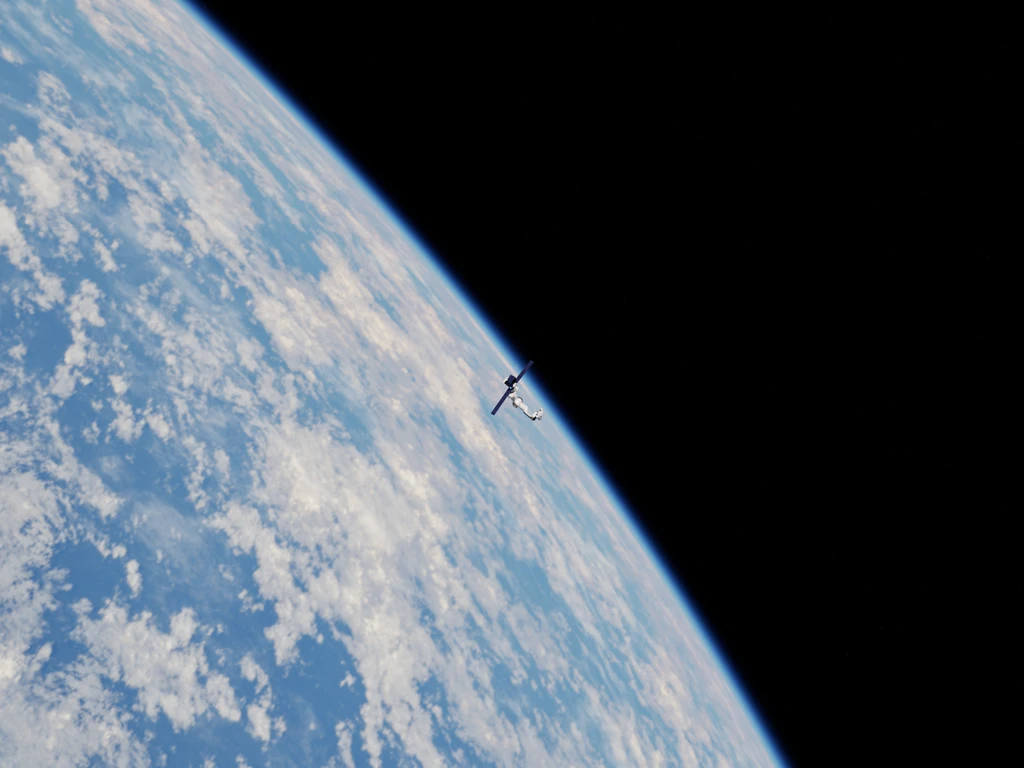
| Episode Length | 10.0s (500 steps) |
| Reward Terms | 2 |
| Default Robot | Generic Orbital Manipulator |
Robots
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.1 | – | |
| penalty_undesired_robot_contacts | Threshold | -0.5 | – |
Mobile Debris Capture (mobile_debris_capture)
Capture of floating debris in microgravity with a floating-base mobile manipulator
| Episode Length | 60.0s (3000 steps) |
| Reward Terms | 10 |
| Default Robot | Generic Orbital Manipulator |
Robots
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.1 | – | |
| penalty_fuel_consumption | Linear | -2 | – | |
| penalty_angular_velocity | Linear | -0.05 | – | |
| penalty_joint_torque | Linear | -0.000025 | – | |
| penalty_joint_acceleration | Linear | -0.0005 | – | |
| reward_distance_end_effector_to_obj | Gaussian | 16 | 0.2 | |
| reward_grasp | SoftThreshold | 32 | – | |
| reward_minimize_rel_lin_vel | Gaussian | 12 | 0.01 | |
| reward_minimize_rel_ang_vel | Gaussian | 24 | 0.03 | |
| penalty_debris_too_far | Linear | -16 | – |
distance_debris_too_far activates penalty_debris_too_far; it does not
terminate the episode. The finite horizon reports truncated. Episode info has
no success, so bounded evaluation reports return only.
Spacewalk (spacewalk)
Humanoid spacewalk: rail-aligned waypoint traversal near spacecraft structure
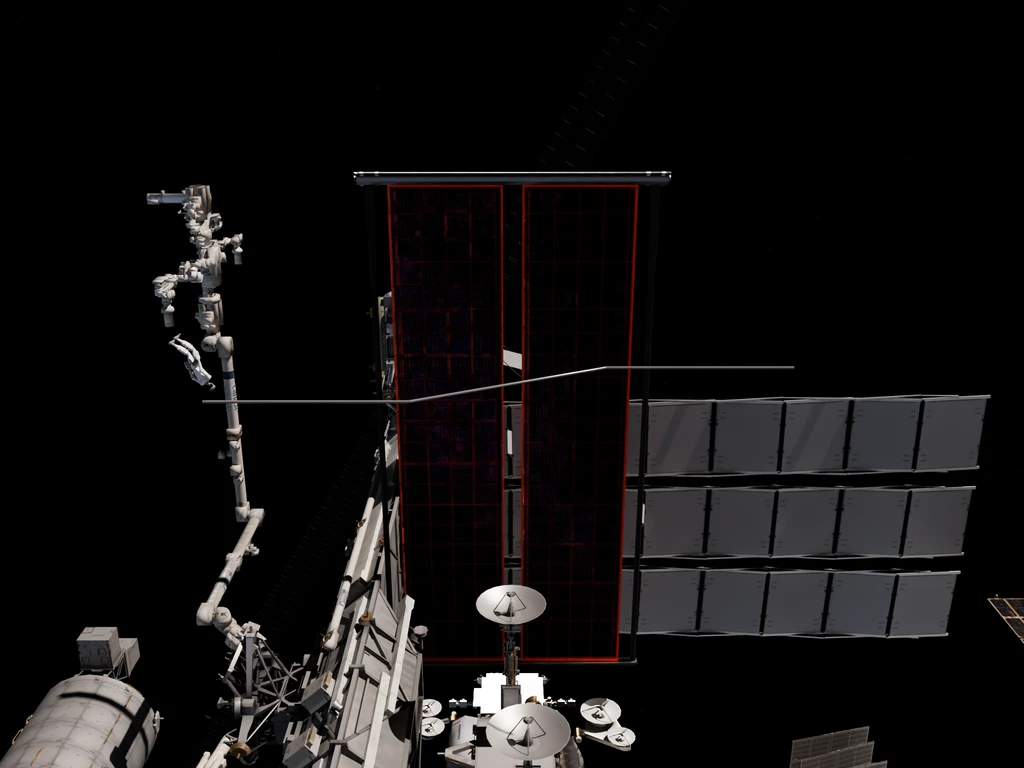
Simulation only; no trained policy ships. Thruster-less humanoid traverses waypoints and station-keeps by pushing off spacecraft structure.
| Mode | Select | Scenery and path | Rail observation / contact |
|---|---|---|---|
| EVA (default) | spacewalk / env.mode=eva | Exterior ISS+Gateway; EVA_WAYPOINT_PATH creates handrails | Rail-distance observation |
| IVA | env.mode=iva / spacewalk_iva | Kibou; base retargets to IVA_WAYPOINT_PATH inside rail-free module | Constant no_handrail_distance; walls unsensed, infer contact from IMU |
Aliases spacewalk_eva / spacewalk_iva make benchmark/launch configuration
explicit. Built-in EVA waypoints clear the station; custom paths must too, or
humanoid, rails, and cameras can enter station meshes. Set
env.use_waypoint_path=false for one random target within ±target_pos_range m
of spacecraft origin, a simpler reaching ablation.
Train and evaluate.
The task checks only the current waypoint each control step and advances at most one waypoint. Passing through an intermediate waypoint between samples does not count as reaching it.
srb agent train --algo dreamer --env spacewalk_eva
srb agent eval --algo dreamer --env spacewalk_eva --model <path/to/checkpoint>
No task-specific DreamerV3 profile exists; the global preset (deter = 8192,
train_ratio = 32) is not tuned for contact locomotion. Evaluation reports:
| Metric | Meaning |
|---|---|
success_rate | Fraction reaching/holding final waypoint |
min_distance_to_target | Minimum sampled distance to the active waypoint; may miss waypoint arrivals |
min_distance_to_final_target | Closest final-waypoint distance; completion measure |
waypoint_progress | Path advancement: index / (num_waypoints − 1) |
dist_to_nearest_handrail | Body-to-rail distance (EVA) |
Diagnose near-zero success. Read min_distance_to_target with
waypoint_progress:
- Low progress + large distance: never nears first waypoint.
- Low progress + small distance: nears a waypoint, cannot advance reliably.
- Progress near 1 + zero success: inspect
min_distance_to_final_target; abovesuccess_radiusmeans goal region not reached, at/below means required hold failed.
EVA scenery. ISSGatewayScenery:
| Setting | Effect / default |
|---|---|
env.scenery.station_template_usd_path | Replace ISS+Gateway with one USD station file |
env.scenery.use_exact_station_mesh_collision | Triangular-mesh collision; default false |
env.scenery.add_handrails, env.scenery.handrail_segment_specs | Control rails aligned to waypoint path |
env.scenery.handrail_specs | X-axis rail shorthand |
Success: final waypoint within success_radius (0.5 m) for
success_stability_steps (10 control steps). Episode-sticky flag records
reaching and briefly holding, not ending there. Resets randomize position in a
±0.5 m box at EVA path start or Kibou origin, orientation fully, linear velocity
±0.1 m/s, angular velocity ±5°/s.
| Control / physics | Constraint |
|---|---|
25 Hz control / 200 Hz physics (env_rate = 5 ms, decimation 8) | Eight contact-resolving push-off substeps; rate pinned because articulation diverges at 50 Hz orbital default |
| Finger joints | Rate limit: stiffness 40, armature 0.001, undamped period about 31 ms |
Observation/action. DreamerV3 vector fields: tf_rot6d_robot (6D
orientation), body-frame target vector tf_pos_robot_to_target, path-mean
dist_to_spacecraft, nearest-rail distance, normalized progress, body-frame
linear/angular velocity, joint positions/velocities, IMU linear acceleration/
angular velocity. No contact state; infer contact from IMU acceleration. Actions:
per-joint position targets; dimension follows actuated USD articulation joints
at runtime. JointPositionToLimits bounds physical limits. Raw observations:
metre-scale distances, [0,1] progress, [-1,1] rot6d. DreamerV3 symlog handles
this range; normalize for other algorithms. No real-hardware validation spec, real
environment generation, or joint-position actuation adapter.
| Episode Length | 20.0s (500 steps) |
| Reward Terms | 9 |
| Default Robot | Unitree G1 |
Robots
Humanoid21 | Humanoid28 | Unitree H1 | Unitree G1
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.5 | – | |
| penalty_angular_velocity | Linear | -2 | – | |
| reward_distance_to_target | Gaussian | 16 | 2.5 | |
| reward_progress | Scaled | 8 | – | |
| reward_approach_velocity | GaussianAlignment | 12 | 0.7854 | |
| reward_reaching | SoftThreshold | 32 | – | |
| reward_stability | Gaussian | 8 | 0.1 | |
| reward_success_hold | Linear | 10 | – | |
| penalty_drift_from_spacecraft | SoftThreshold | -6 | – |
| Reward role | Terms / behavior |
|---|---|
| Guidance | reward_distance_to_target Gaussian (scale 2.5); reward_approach_velocity direction alignment; signed per-step reward_progress. |
| Goal | Dominant reward_reaching: sharp soft-threshold at 0.5 m, independent of success_radius except its 0.5 m default. |
| Hold | reward_stability: low-velocity Gaussian in success region; reward_success_hold: success-streak fraction. |
| Safety | Action-rate/angular-velocity penalties damp jitter; one-sided penalty_drift_from_spacecraft discourages leaving work envelope. |
Waypoints reach ~6 m from work-volume centre, within the drift penalty’s 9 m knee, barely penalizing traversal. Leaving structure is effectively unrecoverable without a push surface; the penalty discourages escape without pulling to origin. Reward favors reaching/holding the goal.
Shaping. Distance/reaching rewards follow the current waypoint, advancing
immediately on arrival. No advance bonus: observe/report waypoint_progress,
never reward it. Intermediate advances transiently drop per-step reward by about
that leg’s distance/reaching rewards. Final goal stays optimal; agents must cross
the local dip instead of camping outside each radius.
Horizon/contact. Truncate at 20 s / 500 steps; no failure termination and
termination always false. Finite horizon (is_finite_horizon=true), so RSL-RL does not bootstrap at the time limit. Rewards cover
traversal/station-keeping only; rigid station, Gateway, and handrail contact are
neither rewarded nor penalized. No grasp reward or penalty for brushing structure.
Locomotion/routes. Without thrusters/ground, internal joint motion cannot
change centre-of-mass velocity; translation needs station/rail push-offs.
Randomized initial drift (±0.1 m/s) covers only part of a multi-metre leg. Rails
cue distance and provide propulsion; at EVA endpoint, brace to arrest velocity.
Rewards measure approach
velocity/progress/distance, not contact; infer push-offs from downstream effects.
EVA: ~12.5 m exterior rail route with lateral turn; 20 s needs ~0.6 m/s average
and efficient push-off chaining. IVA: short, confined Kibou; waypoint spacing
comparable to shared 0.5 m success_radius, favoring final acquisition/station-keeping
over long-range traversal.
Spacewalk Eva (spacewalk_eva)
Humanoid EVA traversal along exterior spacecraft handrails
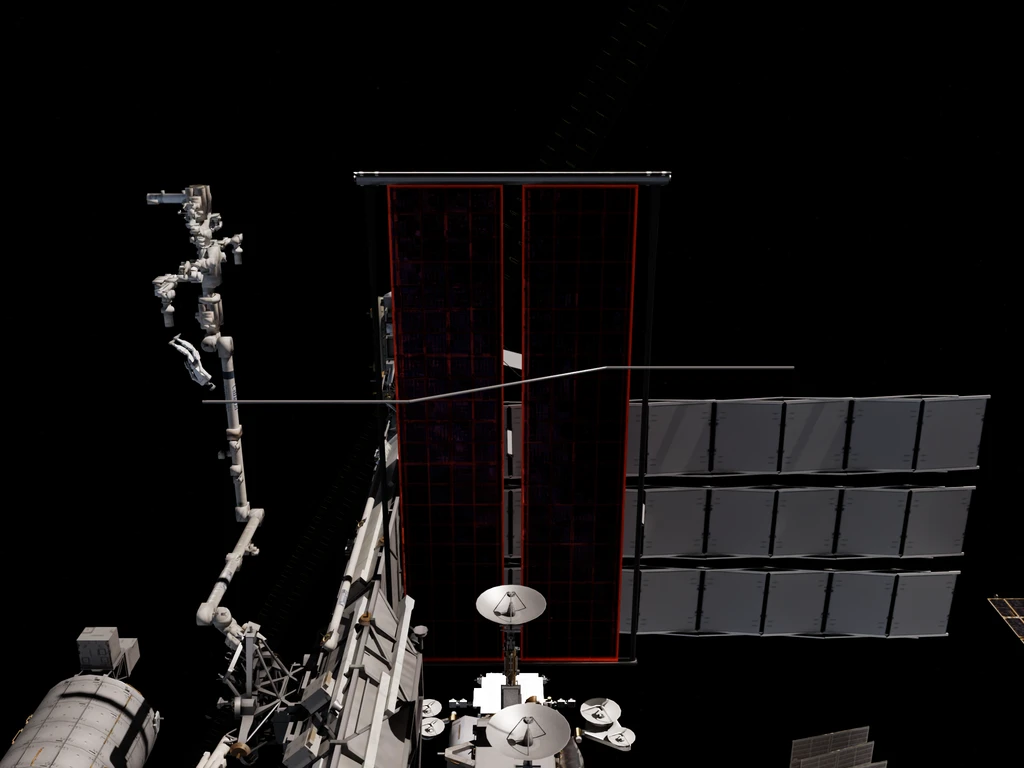
Simulation only; no trained policy ships. See Spacewalk for training and evaluation.
| Episode Length | 20.0s (500 steps) |
| Reward Terms | 9 |
| Default Robot | Unitree G1 |
Robots
Humanoid21 | Humanoid28 | Unitree H1 | Unitree G1
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.5 | – | |
| penalty_angular_velocity | Linear | -2 | – | |
| reward_distance_to_target | Gaussian | 16 | 2.5 | |
| reward_progress | Scaled | 8 | – | |
| reward_approach_velocity | GaussianAlignment | 12 | 0.7854 | |
| reward_reaching | SoftThreshold | 32 | – | |
| reward_stability | Gaussian | 8 | 0.1 | |
| reward_success_hold | Linear | 10 | – | |
| penalty_drift_from_spacecraft | SoftThreshold | -6 | – |
Evaluation. Episode-end info publishes success; bounded evaluation reports success rate and return.
Spacewalk Iva (spacewalk_iva)
Humanoid IVA traversal inside the Kibou module
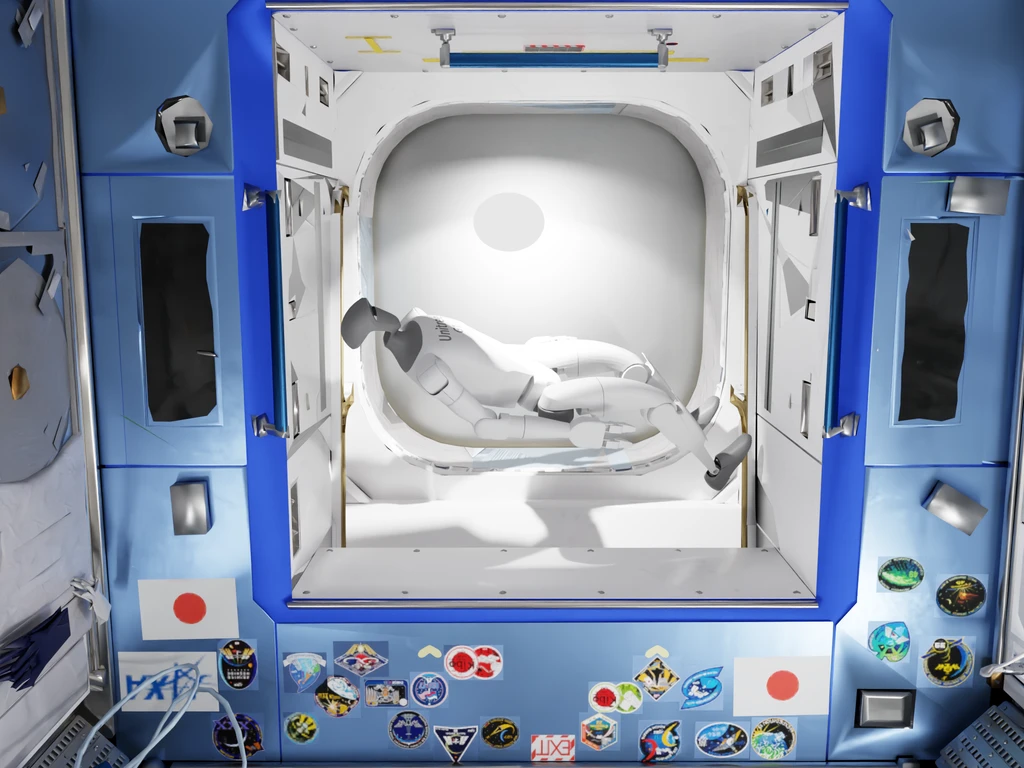
Simulation only; no trained policy ships. See Spacewalk for training and evaluation.
| Episode Length | 20.0s (500 steps) |
| Reward Terms | 9 |
| Default Robot | Unitree G1 |
Robots
Humanoid21 | Humanoid28 | Unitree H1 | Unitree G1
Rewards
| Term | Type | Weight | Scale | Notes |
|---|---|---|---|---|
| penalty_action_rate | Linear | -0.5 | – | |
| penalty_angular_velocity | Linear | -2 | – | |
| reward_distance_to_target | Gaussian | 16 | 2.5 | |
| reward_progress | Scaled | 8 | – | |
| reward_approach_velocity | GaussianAlignment | 12 | 0.7854 | |
| reward_reaching | SoftThreshold | 32 | – | |
| reward_stability | Gaussian | 8 | 0.1 | |
| reward_success_hold | Linear | 10 | – | |
| penalty_drift_from_spacecraft | SoftThreshold | -6 | – |